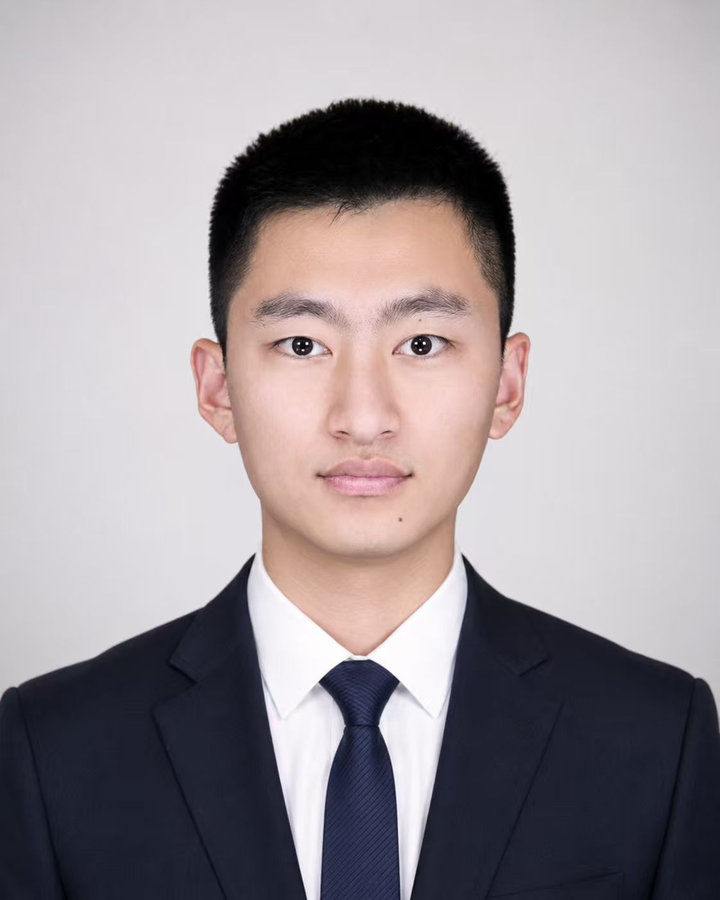
Tianjian Zhou 周天健
Ph.D. researcher · NUDT博士研究生 · 国防科技大学
First author of EquiSSL, DAGA, CORE and SDI. Works on self-supervised representation learning, efficient adaptation and 360° vision.
EquiSSL、DAGA、CORE、SDI 的第一作者。研究自监督表征学习、高效适配与 360° 视觉。
Research group · College of Systems Engineering, NUDT 研究团队 · 国防科技大学系统工程学院
We study how visual models learn, adapt and use representations: what should stay stable when inputs change, how little supervision or adaptation is enough, and how a representation can serve recognition, generation and multi-modal perception.
我们研究视觉模型如何学习、适配与使用表征:当输入变化时什么应当保持稳定,多少监督或适配才算足够,以及表征如何同时服务于识别、生成与多模态感知。
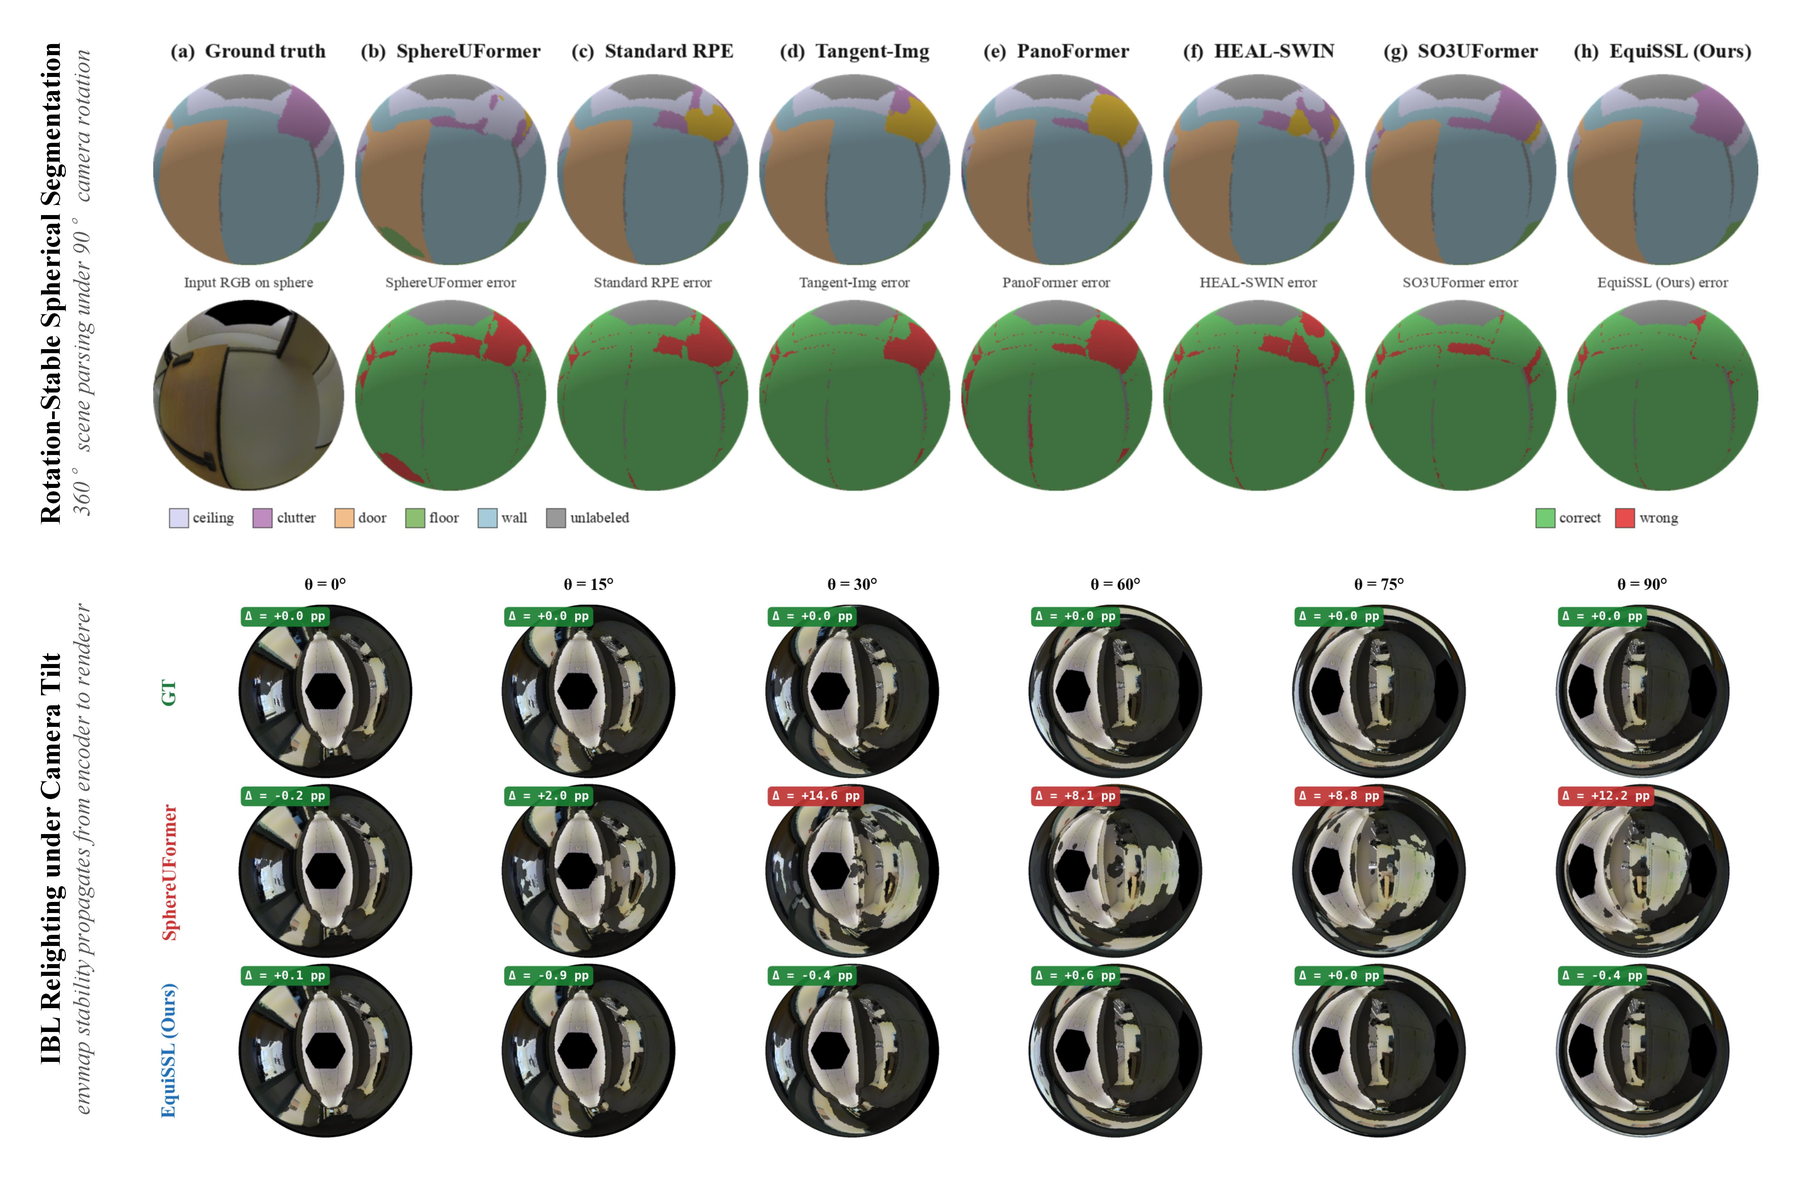
ACM TOG · SIGGRAPH Asia 2026
Spherical transformers lose over half their accuracy when the camera rotates. EquiSSL makes the attention bias invariant to the local gauge — with zero added parameters — and turns rotation-consistent self-supervision into a label-efficiency lever.
球面 Transformer 在相机旋转时会损失超过一半的精度。EquiSSL 让注意力偏置对局部规范保持不变——且不增加任何参数——并把旋转一致的自监督变成提升标签效率的杠杆。
EquiSSL is accepted by ACM Transactions on Graphics (SIGGRAPH Asia 2026 Journal Track).
EquiSSL 被 ACM Transactions on Graphics 接收(SIGGRAPH Asia 2026 期刊轨)。
CORE — Less Is More — is published in IEEE Transactions on Neural Networks and Learning Systems.
CORE(Less Is More)正式发表于 IEEE Transactions on Neural Networks and Learning Systems。
DAGA is accepted to NeurIPS 2026 — dynamic attention-guided adaptation for frozen self-supervised vision transformers.
DAGA 被 NeurIPS 2026 接收——面向冻结自监督视觉 Transformer 的动态注意力引导适配。
SDI is accepted by Pattern Recognition — semantic-guided augmentation with foundation-model priors.
SDI 被 Pattern Recognition 接收——利用基础模型先验的语义引导数据增广。
P-SLCR is published in AAAI 2026 — unsupervised point-cloud semantic segmentation via prototype structure learning.
P-SLCR 发表于 AAAI 2026——基于原型结构学习的无监督点云语义分割。
Minimal contrastive objectives and semantic augmentation for label-efficient visual representations — from removing unnecessary components to learning from foundation-model priors.
极简对比目标与语义增广,面向标签高效的视觉表征——从删去不必要的组件,到利用基础模型先验学习。
Read more阅读更多Lightweight, input-dependent adaptation of frozen foundation models — with 1.4% extra parameters, and a clearer picture of what a representation pipeline really needs.
面向冻结基础模型的轻量、输入相关适配——仅增加 1.4% 参数,并更清楚地理解表征流程真正需要什么。
Read more阅读更多Contrastive manifold autoencoding and latent diffusion, for latent spaces that keep the high-frequency structure that VAE latents lose.
对比流形自编码与潜在扩散,保留 VAE 潜空间中容易丢失的高频结构。
Read more阅读更多Asymmetric infrared–visible fusion, heterogeneous retrieval, point-cloud understanding, and rotation-stable spherical vision — geometry as one tool among several.
非对称红外—可见光融合、异构检索、点云理解与旋转稳定的球面视觉——几何只是其中一种工具。
Read more阅读更多
Ph.D. researcher · NUDT博士研究生 · 国防科技大学
First author of EquiSSL, DAGA, CORE and SDI. Works on self-supervised representation learning, efficient adaptation and 360° vision.
EquiSSL、DAGA、CORE、SDI 的第一作者。研究自监督表征学习、高效适配与 360° 视觉。
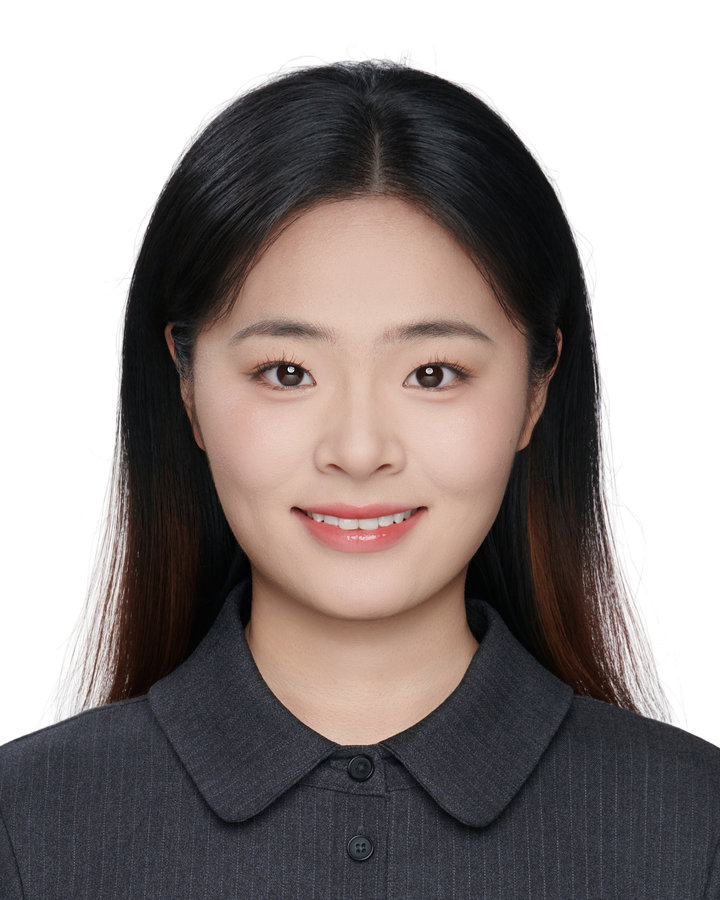
Ph.D. researcher · NUDT博士研究生 · 国防科技大学
Co-author of EquiSSL and DAGA, and co-first author of CMAE (ICME '26 Oral). Focuses on multi-modal representation learning and fusion.
EquiSSL 与 DAGA 合作者,CMAE(ICME '26 Oral)共同第一作者。关注多模态表征学习与融合。
Collaboration合作
For collaborations, talks, reviewing or anything about representation learning and visual intelligence, write to us — we read every message. 无论是合作、报告、审稿,还是表征学习与视觉智能的任何问题,都欢迎来信——我们会认真读完每一封邮件。